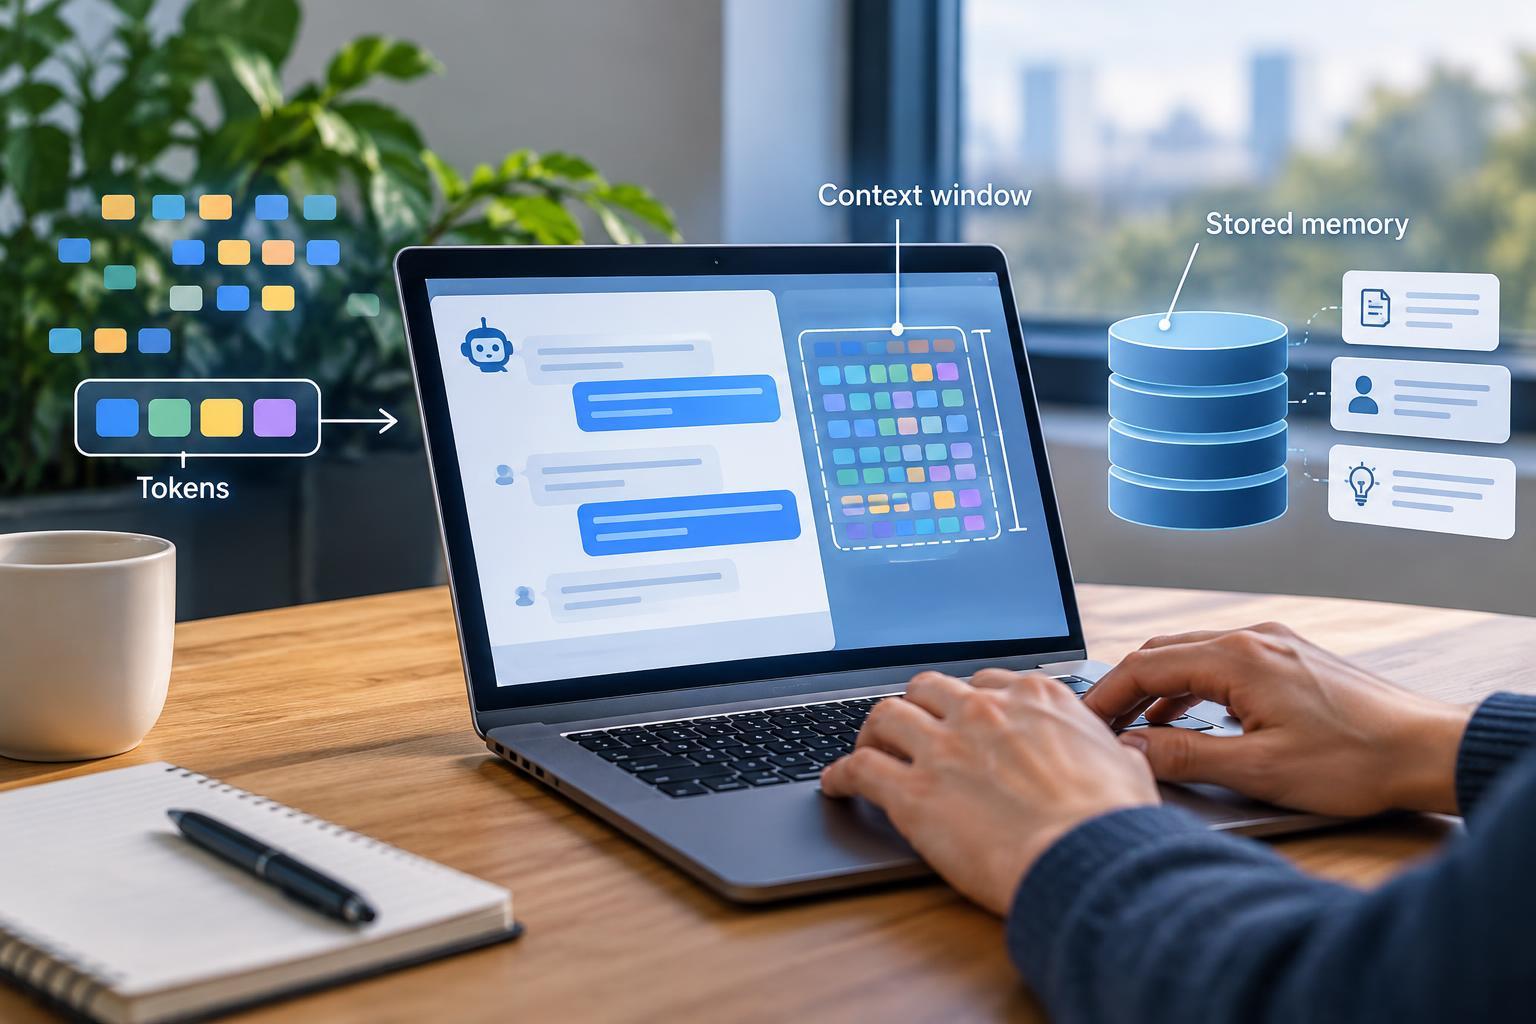
Tokens Are the Units a Model Processes
When you send text to a language model, it is usually converted into tokens before the model processes it. A token may represent a whole word, part of a word, punctuation, or a space combined with nearby text. The rules come from the model’s tokenizer, so the same sentence can produce different token counts in different systems.
This is why word counts and token counts are not interchangeable. A familiar English word might fit into one token, while an unusual technical term may require several. Code, long numbers, and text in different languages can also tokenize differently. A document’s page count is therefore a poor guide to whether it will fit within a model’s limits.
Tokens matter because they are a basic unit of processing. Many AI services use token counts to measure input and output usage. Longer inputs and answers generally require more processing, although speed and cost also depend on the model and how the service operates.
The Context Window Is a Limited Working Space
A context window is the maximum amount of tokenized material a model can consider during a generation task. Think of it as a working desk rather than a permanent archive: only the material placed on that desk is directly available for the current response. A larger desk holds more information, but it is still finite.
That space may contain more than your latest message. System instructions, conversation history, retrieved passages, tool results, and other application-provided content can all occupy part of the input. In many systems, input and generated output must fit within a shared overall limit, while separate input or output limits may also apply. The exact arrangement depends on the model and service.
When a request exceeds the available budget, the application may reject it, remove older messages, shorten documents, or replace parts of the conversation with summaries. These choices happen at the product level; the model does not necessarily decide what to retain. Consequently, an earlier message visible in a chat interface may no longer be present in the model’s current input.
Why Longer Context Is Technically Difficult
Many language models use attention mechanisms to relate tokens to one another. In a standard full-attention design, the number of token-to-token relationships grows roughly with the square of the sequence length. Doubling the sequence can therefore create about four times as many attention relationships, although actual runtime and memory use depend on implementation.
Generating an answer also requires maintaining intermediate information about the sequence. Many systems cache representations of earlier tokens so they do not have to recompute everything for every new token. These caches consume memory and generally grow as the sequence becomes longer. Efficient attention methods, cache optimizations, and alternative architectures can reduce these costs, but they do not make context unlimited.
There is also a reliability challenge. Models need suitable training and position-handling methods to use long sequences effectively. Accepting a large input is not the same as accurately connecting every detail within it. Performance can vary with information placement, distracting material, and the number of separate facts a task requires the model to combine.
Context, Training, and Stored Memory Are Different
A model’s learned parameters are different from its current context. Training adjusts those parameters to capture patterns from training material. During ordinary chat inference, adding a fact to the conversation does not automatically update the model’s parameters or teach it that fact permanently.
Some AI products offer memory features, but these usually operate outside the core model. An application may save preferences, summaries, or other information and insert relevant items into a later request. Similarly, retrieval systems search stored documents and supply selected passages. Both approaches can make information available across sessions without placing an entire archive in every context window.
This distinction explains why apparent forgetting has several possible causes. A detail may have been removed from the context, omitted from a summary, or missed during retrieval. Even when it remains available, the model may fail to use it correctly. A confident answer is not proof that the system retained or checked the relevant information.
How to Work Within the Limits
Start by giving the model a clear task and the information needed to complete it. For long documents, use a staged process: identify relevant sections, extract important facts, and then ask for a synthesis. Keep references to the original passages so summaries can be checked rather than treated as perfect substitutes.
For extended conversations, maintain a compact handoff note containing the goal, constraints, decisions, and unresolved questions. Ask the model to flag missing evidence instead of filling gaps. When precision matters, verify its answer against the source material. Larger context windows are useful, but focused inputs and deliberate checks often matter more than simply supplying more text.


