Start With the Problem You Need to Solve
A general-purpose language model may write clearly yet struggle with an organization’s product manuals, internal terminology, or specialized workflows. Adapting it requires identifying what is missing: access to the right information, reliable task behavior, or both. That distinction matters more than choosing the most sophisticated technique.
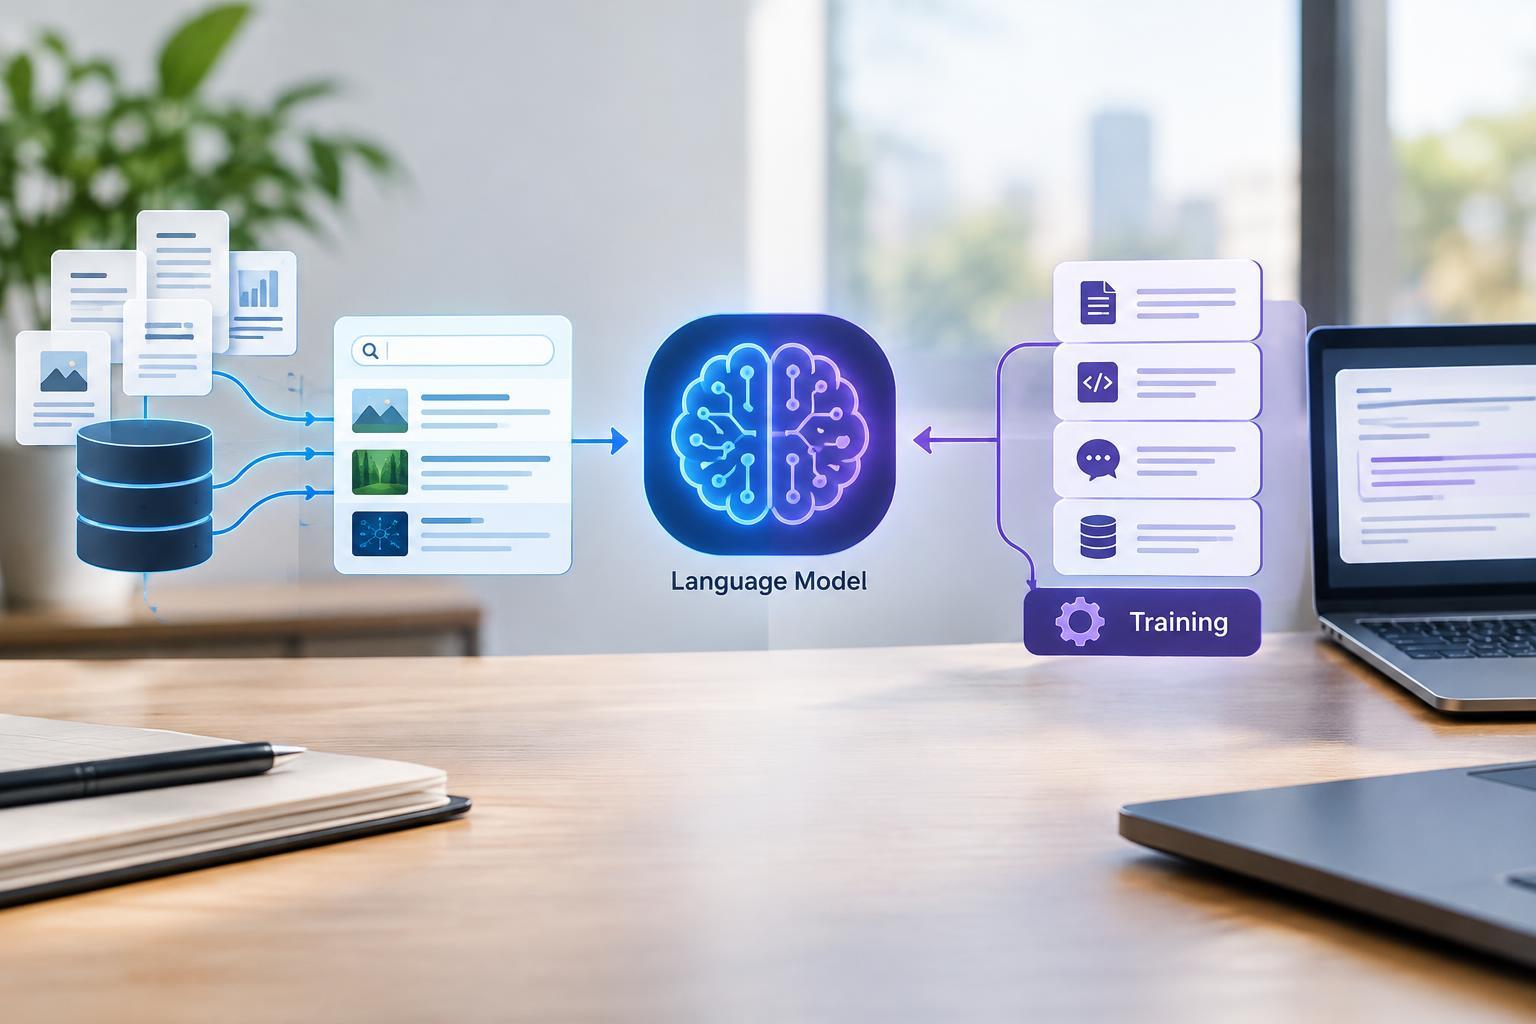
Retrieval-augmented generation, or RAG, supplies relevant information when a request arrives. Fine-tuning changes a model’s parameters through additional training. A useful starting rule is to consider RAG when the model needs specific facts and fine-tuning when it needs to perform a task more consistently. This is a guideline, not a strict boundary: fine-tuning can teach domain knowledge, and retrieved examples can influence behavior.
How RAG Brings Knowledge Into the Conversation
A RAG system searches a collection of documents or other information sources before generating an answer. It typically divides material into passages, indexes them, and retrieves candidates relevant to the user’s question. Search may use keywords, semantic similarity, or a combination. Selected passages are then placed in the model’s context alongside instructions and the question. The model’s underlying parameters do not change.
Consider an assistant answering questions about equipment maintenance. Instead of relying on what the model learned during its original training, the system retrieves passages from the appropriate manual. This makes it easier to incorporate revised documentation and show supporting references. However, retrieval can select the wrong equipment version, overlook an exception, or miss information spread across several documents. Access to a source does not guarantee a faithful answer, and a generated citation still needs to support the associated claim.
How Fine-Tuning Changes Model Behavior
Fine-tuning trains an existing model on additional examples. For many business applications, those examples pair realistic inputs with desired outputs: a support message with its correct classification, a technical note with a standardized summary, or a request with a properly structured response. Depending on the method, training updates all model parameters or a smaller set of additional parameters.
This approach can improve consistency in terminology, formatting, tone, and repeated decision patterns. It can also help with specialized tasks that prompting alone handles unreliably. But fine-tuning is not a dependable substitute for a searchable reference library. Facts learned through training can be difficult to update, inspect, or trace to a source. Weak examples may reinforce mistakes, while overly narrow training can reduce performance on inputs unlike the training set. Success depends on representative examples and evaluation, not simply on having more data.
Compare Freshness, Traceability, and Operational Cost
RAG is often the stronger starting point when information changes regularly or answers need documentary support. Updating an indexed collection can be simpler than retraining a model, although document ingestion, versioning, and search quality still require maintenance. Fine-tuning is often more suitable for stable, recurring behaviors, such as converting notes into a consistent schema. It may reduce lengthy instructions or repeated examples in prompts, but this benefit must be measured.
Neither approach is automatically cheaper or faster. RAG adds retrieval infrastructure, search time, and potentially long contexts. Fine-tuning adds data preparation, training, model management, and regression testing. Both require privacy and security controls. Retrieval must enforce access permissions before content reaches the model, and retrieved text should be treated as untrusted data rather than instructions. Fine-tuning data also needs careful handling because trained models may reproduce sensitive material.
Use Both When Knowledge and Behavior Matter
Many applications need both current reference material and dependable task execution. A technical support assistant, for example, might retrieve approved troubleshooting instructions while using a fine-tuned model to ask concise clarifying questions and produce a consistent response structure. Retrieval provides the evidence; fine-tuning shapes how the model handles the task.
A practical development sequence is to begin with a capable base model and clear instructions. Add retrieval if the main failures involve missing or outdated knowledge. Consider fine-tuning if persistent errors concern format, terminology, or task execution despite adequate context. This sequence helps avoid training a model to compensate for problems that actually originate in poor document quality or ineffective search.
Evaluate the Whole System Before Committing
Create a held-out test set that reflects real requests, including ambiguous questions, conflicting documents, and cases where no answer is available. Compare a prompting-only baseline with RAG, fine-tuning, or a combined system. Assess factual correctness, task completion, evidence support, format compliance, appropriate abstention, latency, and cost. Keep test examples separate from training data.
For RAG, check retrieval quality separately from answer quality: did the system find the necessary evidence, and did the model use it correctly? For fine-tuning, check whether improvements extend to unfamiliar examples without harming other capabilities. Choose the simplest configuration that meets your requirements, then retest when documents, models, or workflows change.


