What Overfitting and Underfitting Actually Mean
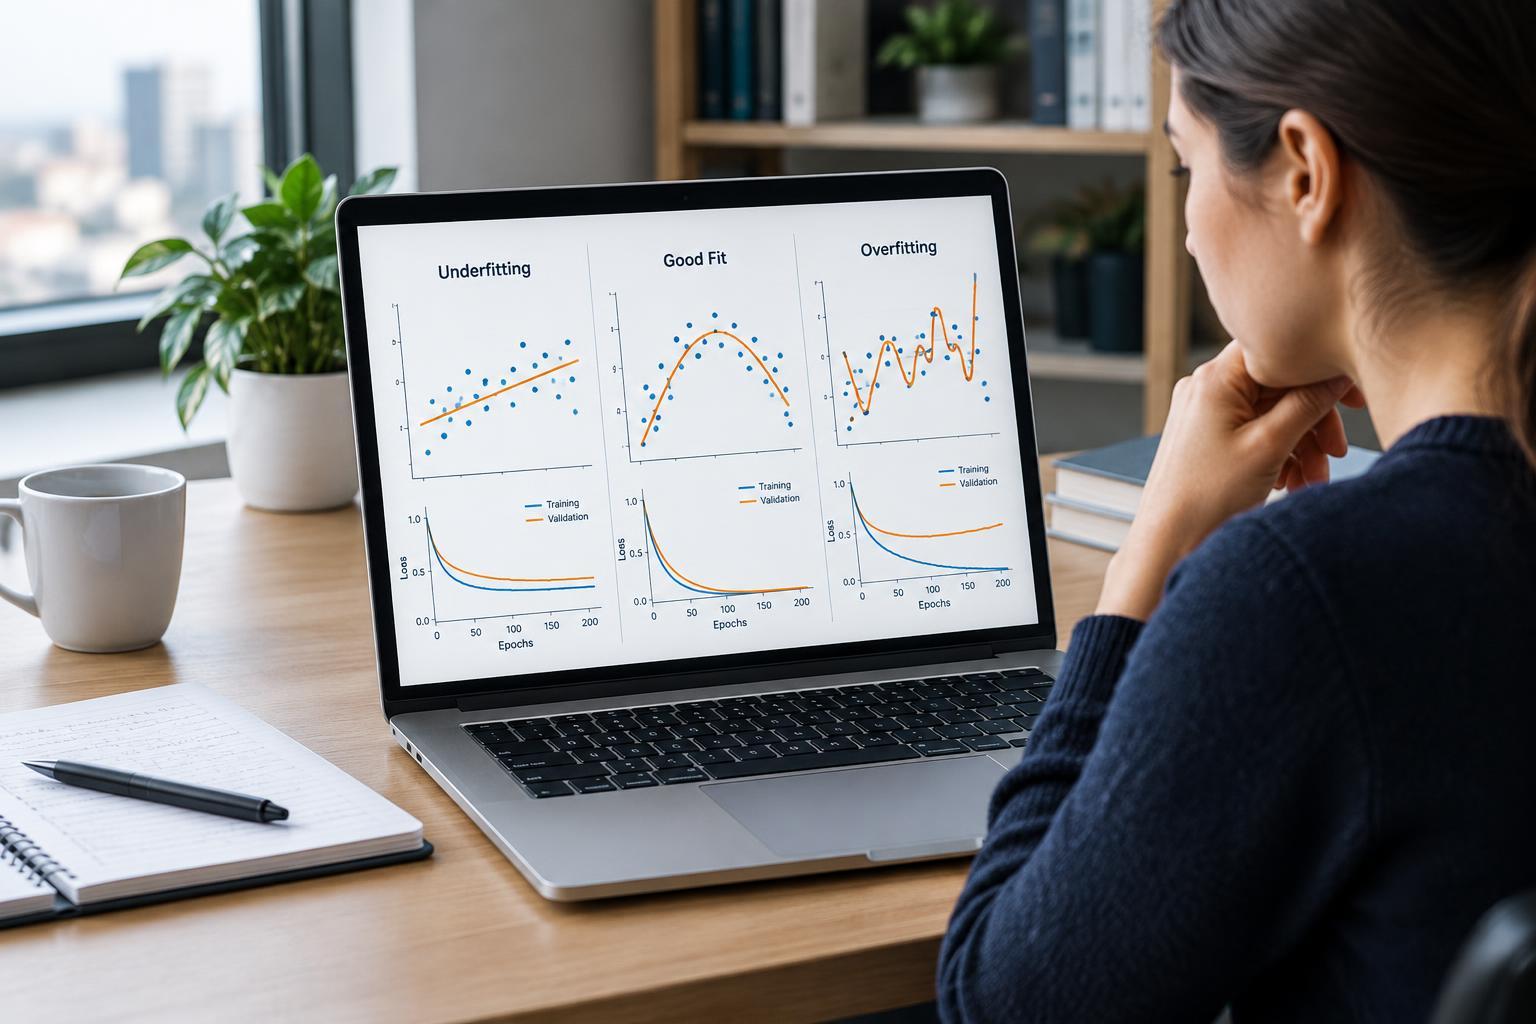
The goal of model training is not simply to achieve a strong score on familiar examples. It is to learn patterns that remain useful on unseen data. Underfitting happens when a model fails to capture important structure in the problem. Overfitting happens when it learns details specific to the training sample, including noise, that do not generalize.
Imagine predicting delivery times from distance, traffic conditions, and package characteristics. An overly simple model might miss how congestion changes the effect of distance, producing weak predictions even on its training data. An overly flexible model might memorize unusual deliveries and appear highly accurate during training, only to struggle with new orders.
These problems are often described through the bias–variance trade-off: restrictive assumptions can prevent learning useful relationships, while excessive sensitivity to a particular sample can harm generalization. This is a useful framework, not a complete diagnosis. Poor data quality, missing features, optimization failures, and changing conditions can produce similar symptoms.
Recognize the Signs With Training and Validation Results
Compare performance on the training set with performance on a separate validation set. Underfitting typically produces weak results on both. Overfitting typically produces much stronger training results than validation results. Judge “weak” against a meaningful baseline, such as predicting the most common class, rather than assuming that a particular score is universally good or bad.
Plot training and validation loss across training steps. When training loss continues falling while validation loss begins rising, the model is likely becoming more specialized to the training data. If both losses remain high and flatten early, investigate underfitting or a training problem. A small gap alone does not prove success: both results could be poor.
Learning curves that plot performance against training-set size provide another clue. If validation performance improves as more examples are added and the gap narrows, additional representative data may help. If both curves settle at an unsatisfactory level, more of the same data may offer limited benefit without better features, a more suitable model, or improved optimization.
Check the Evaluation Before Changing the Model
A train–validation gap is evidence to investigate, not automatic proof of overfitting. The sets may differ in important ways. For example, training on one customer population and validating on another can reveal distribution shift. Review feature ranges, missing values, class balance, and label quality across splits before deciding that model complexity is the main issue.
Design splits to reflect how predictions will be used. For forecasting, train on earlier observations and validate on later ones. When multiple records belong to the same person, device, or organization, consider keeping each group within a single split. Otherwise, closely related examples can make validation performance look better than it really is.
Prevent leakage by fitting learned preprocessing steps, such as scaling, imputation, and feature selection, only on the training portion of each split. Use validation data or suitable cross-validation for development, and reserve an untouched test set for final assessment. Choose metrics that match the task: accuracy alone can conceal poor performance on a rare but important class.
Address Underfitting by Finding the Constraint
First confirm that training is functioning correctly. Check that labels align with examples, the loss suits the task, and input transformations are consistent. For iterative models, examine whether the learning rate is preventing stable progress or whether training stopped too soon. Longer training can help incomplete optimization, but it cannot fix a model that lacks the necessary expressive power.
If the setup is sound, increase capacity carefully. Depending on the model, this might mean allowing deeper trees, adding useful interactions, or choosing a more flexible model family. Reduce overly strong regularization when it is suppressing meaningful patterns. Better features can also help a simple model represent relationships it previously could not express.
Inspect errors by subgroup and example type. Consistent failures may expose missing information or unreliable labels rather than insufficient capacity. When the available inputs do not contain enough predictive signal, adding complexity will not solve the underlying limitation.
Reduce Overfitting and Verify the Improvement
Try limiting model complexity or strengthening regularization. Options include restricting tree depth, increasing minimum leaf size, or applying stronger penalties to model parameters. For neural networks, weight decay, dropout, and early stopping are common tools. Their effectiveness depends on the task, so select settings using validation results rather than assuming stronger intervention is always better.
More representative training data can help models distinguish stable patterns from accidental ones. Data augmentation may also help when transformations preserve the correct label and reflect plausible real-world variation. Duplicating existing examples does not add comparable information, and unrealistic augmentation can make performance worse.
Change one major factor at a time, record the result, and use consistent evaluation splits. Where practical, repeat experiments across seeds or appropriate cross-validation folds to assess variability. Accept a lower training score if validation performance improves reliably. Once development decisions are complete, evaluate on the reserved test set: the objective is dependable performance on new cases, not a perfect training score.


