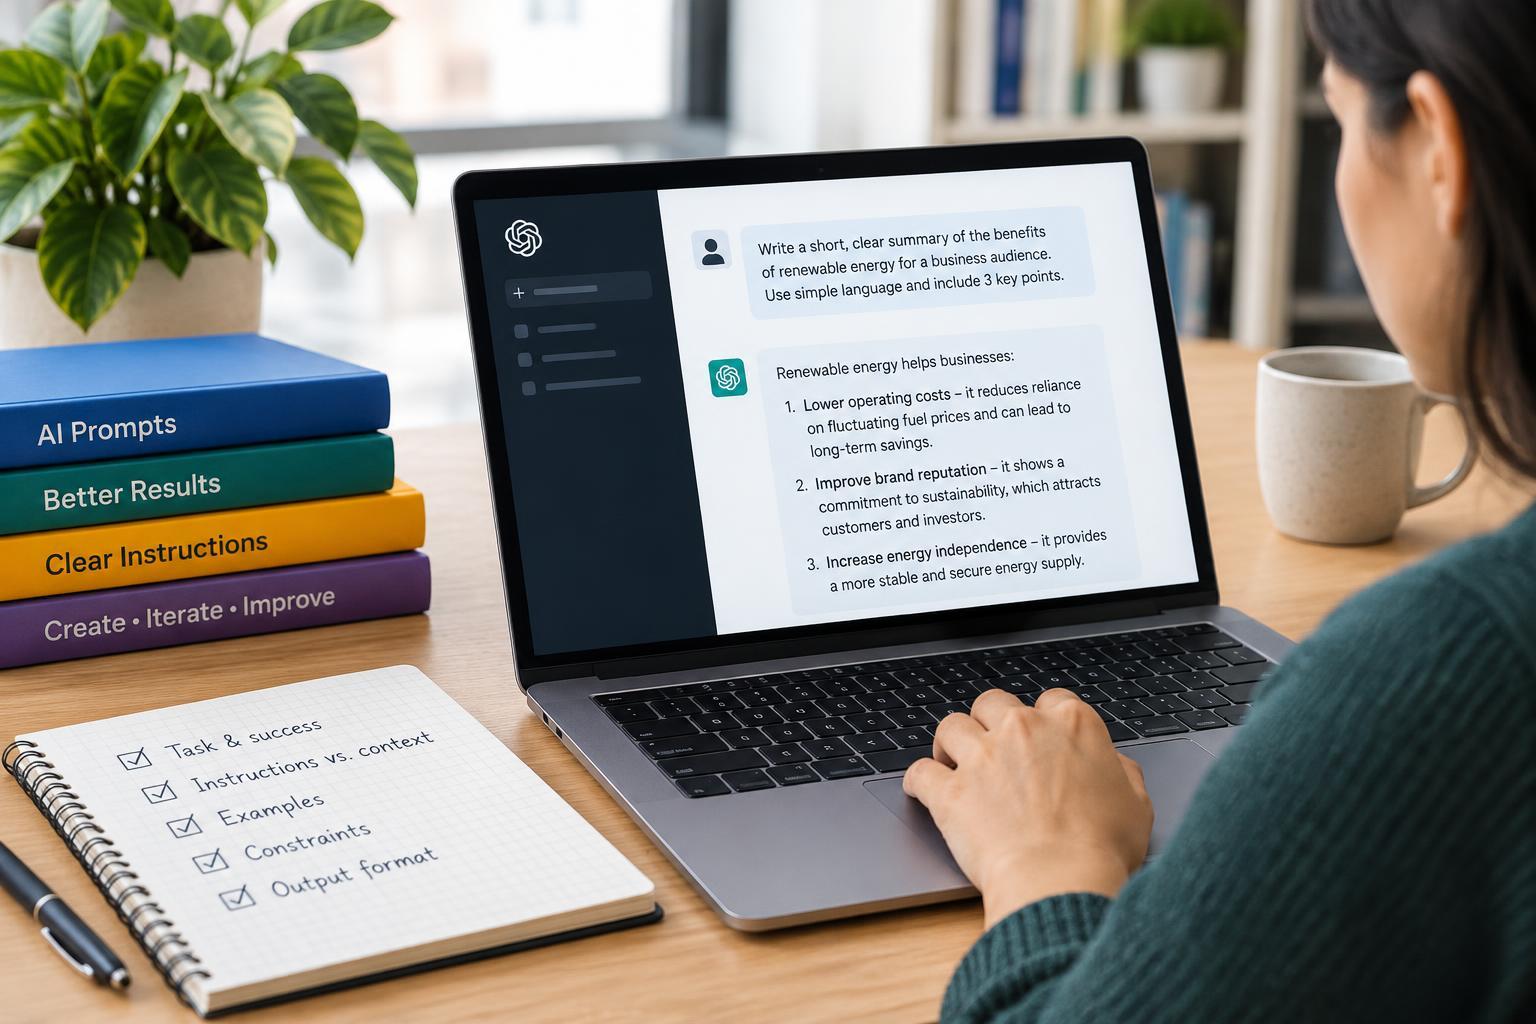
Start with a task and a definition of success
A useful AI prompt is less like a search query and more like a short work brief. It explains what the model should do, what information it should use, and what a successful response looks like. Clear prompts reduce avoidable ambiguity, although they cannot guarantee factual accuracy or consistent results.
Begin with a specific action: summarize, compare, extract, rewrite, classify, or draft. Then name the material and intended audience. “Summarize these meeting notes for the project manager” gives more direction than “Help with these notes.” Add the purpose when it affects the answer, such as identifying decisions and unresolved questions rather than recounting the discussion.
Define success using observable requirements. For example: “Summarize the notes in no more than 150 words. Include decisions, action owners, and open questions. Do not assign an owner unless the notes identify one.” This establishes both the task and a standard for checking the result. A role such as “experienced editor” can suggest a perspective, but it is not a substitute for concrete instructions.
Separate instructions from context and source material
Context helps the model make relevant choices. For a customer email, useful context might include the customer's concern, the approved resolution, and the desired tone. Unrelated company history usually adds noise. Supply information that could change the response, and remove details that have no bearing on the task.
Use clear labels to distinguish the work brief from the material being processed. A prompt can contain sections named Task, Audience, Source material, and Requirements. Explicit boundaries are particularly helpful when the source includes emails, documents, or quoted conversations that themselves contain requests.
Tell the model how to handle gaps: “Use only the supplied notes. If a deadline is missing, write ‘Not specified’ rather than inferring one.” When missing information would substantially change the answer, ask for clarification before drafting. Otherwise, allow a limited response that clearly identifies what is unknown. Labels improve clarity, but they are not a security boundary; applications processing untrusted content still need safeguards beyond prompt wording.
Use examples to demonstrate the pattern you want
Examples are valuable when an instruction is open to interpretation. Words such as “concise,” “friendly,” or “technical” mean different things to different readers. A short example can demonstrate the intended level of detail, wording, or classification rule more efficiently than a long list of adjectives.
For a support-ticket classifier, show both input and expected output: “Input: I was charged twice for the same order. Output: Billing.” Add contrasting examples for categories that are easy to confuse. If the distinction between a software defect and a feature request matters, demonstrate each rather than supplying several nearly identical billing examples.
Keep examples consistent with the written rules. If you request one sentence but provide a three-paragraph sample, the prompt sends conflicting signals. Explain which features should be copied: “Match the structure and level of detail, not the names or facts.” Examples should demonstrate a pattern, not accidentally introduce information into the final response.
Set constraints that improve usefulness
Constraints define the acceptable boundaries of a response. Useful constraints cover length, scope, tone, evidence, and exclusions. “Write for readers with no programming background, define unfamiliar terms, and avoid product recommendations” is easier to apply than “Make it accessible and unbiased.” Prefer requirements you can actually inspect.
Separate essential rules from preferences. A requirement to use only supplied information is more important than a preference for lively prose. State priorities when rules could compete: “Prioritize factual completeness over the target length, but keep the response under 300 words.” Avoid combinations that cannot reasonably be satisfied, such as demanding exhaustive coverage in two short sentences.
More constraints do not automatically produce better answers. Repeated warnings and overlapping style rules can obscure the main task. Start with the smallest set that makes the output usable, then add requirements in response to specific failures. Avoid including confidential or personal information unless the tool and your organization's policies permit that use.
Specify the output format, then test and refine
Choose a format that matches the next step. Paragraphs suit explanation, tables support comparisons, and structured fields help with extraction. For JSON, specify field names, value types, and how missing values should appear. Requesting “JSON only” communicates intent, but software should still parse and validate the result. Use schema-enforced output features when available.
A reusable prompt might read: “Task: Extract action items from the meeting notes below. Source: [insert notes]. Requirements: Include only explicitly stated actions; do not infer owners or deadlines. Output: A JSON object with an actions array. Each item must contain task, owner, and deadline. Use strings for stated values and null for missing owners or deadlines. If no actions are stated, return an empty array. Return no additional text.”
Test your prompt with ordinary inputs and awkward cases: incomplete notes, ambiguous wording, and material containing no relevant information. Inspect factual support as well as formatting. Revise the instruction connected to the failure instead of adding vague demands to “be better.” Prompt writing works best as a small design-and-test cycle, with human review wherever mistakes would matter.


