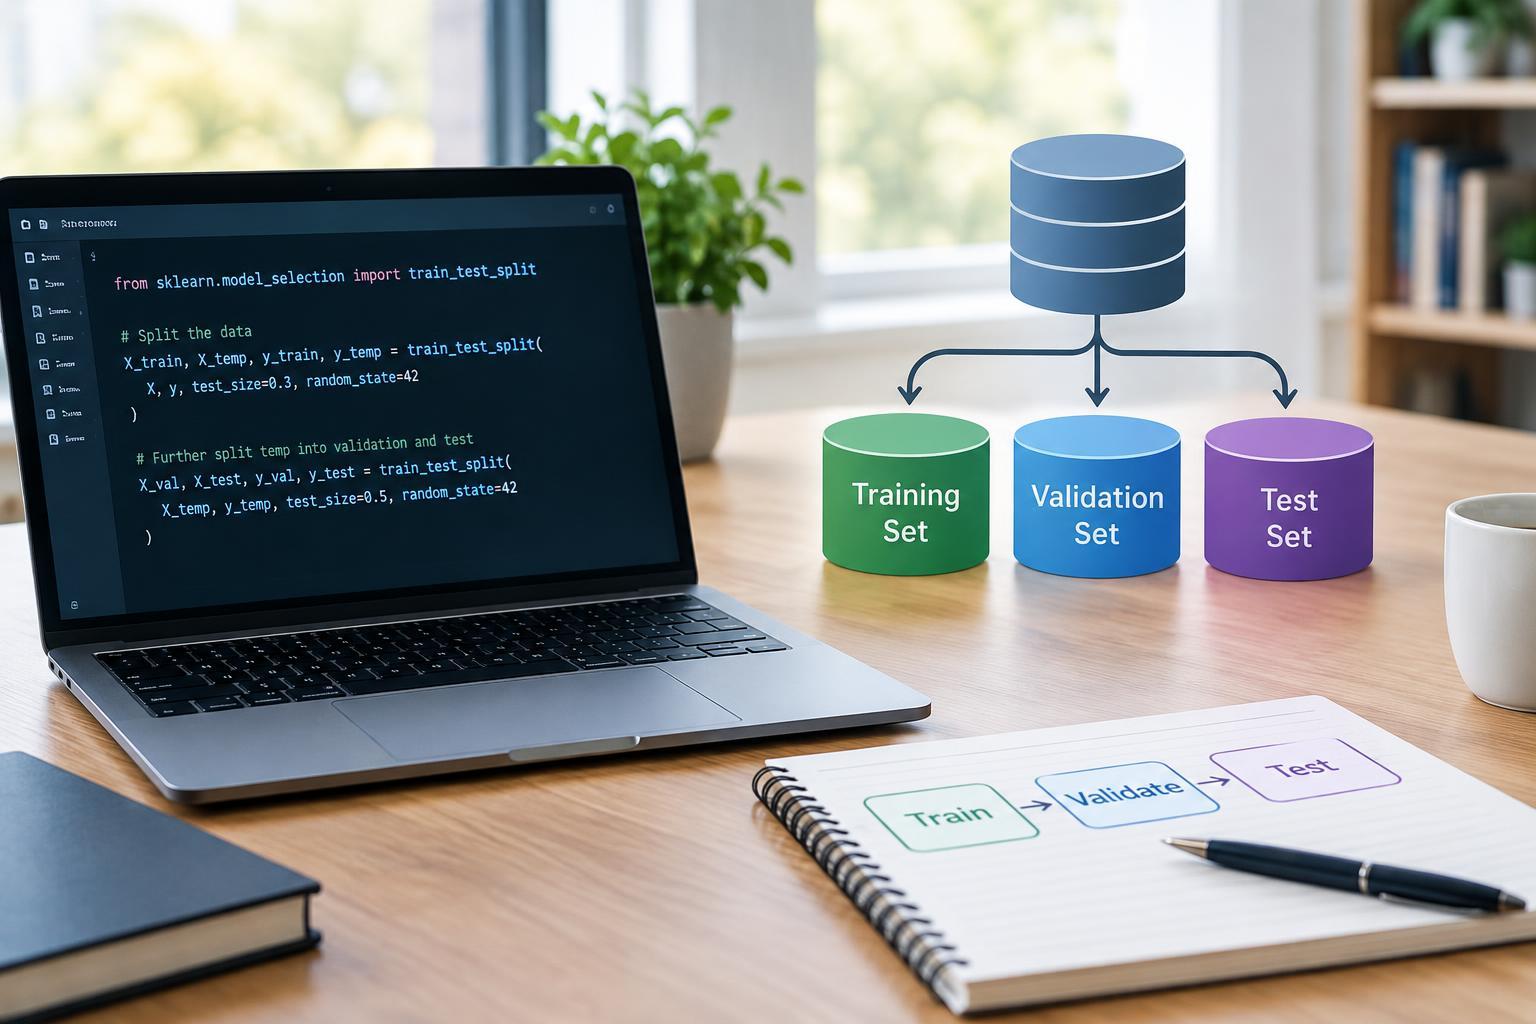
Give Each Dataset a Distinct Job
A model can perform impressively during development and still disappoint in production. One reason is data leakage: information that would not legitimately be available during training or prediction influences the model or its evaluation. A good split creates boundaries that make evaluation more representative of real use.
The training set is where the model learns its parameters. The validation set supports development decisions, such as choosing features, comparing algorithms, tuning hyperparameters, setting decision thresholds, and selecting when to stop training. Because those decisions respond to validation results, validation performance is not an independent final assessment.
The test set is reserved for evaluating the selected approach after development decisions are fixed. Treat it as a final check, not another optimization target. Repeatedly adjusting a model after inspecting test results makes that dataset part of the development process, even if its rows never enter model training.
Split According to the Prediction Task
Before choosing percentages, define what one prediction represents and what will be unfamiliar at deployment. Will the model encounter new customers, future transactions, unseen devices, or more records from known users? The split should reproduce that situation as closely as practical.
A random split can work when examples are reasonably independent and come from a similar population. For classification, stratification can preserve approximate class proportions across subsets. However, neither randomization nor stratification prevents related examples from crossing boundaries.
Use a group-based split when multiple rows belong to an entity that should remain unseen during evaluation, such as a patient, household, machine, or source document. Use a chronological split when predicting future outcomes. If deployment involves both future data and unseen entities, the evaluation design may need both time and group restrictions.
Choose Sizes That Support Meaningful Evaluation
There is no universally correct split ratio. A 70/15/15 allocation is a reasonable starting example, not a rule. Training needs enough examples to learn useful patterns, while validation and test sets need enough relevant cases to reveal meaningful differences and failure modes.
For rare outcomes, percentages alone can be misleading. A seemingly large test set might contain very few positive examples. Inspect class counts, group counts, and coverage of important operating conditions. Keep the test distribution aligned with intended use; artificially balancing it can change how some metrics should be interpreted.
When data is limited, cross-validation can support model selection more efficiently than one validation split. Each fold must preserve the same group or time boundaries required by the task. Keep a separate final holdout when feasible, or use nested cross-validation to separate model selection from performance estimation. Record split membership and any random seed for reproducibility.
Fit Preprocessing Only on Training Data
Separate the datasets before fitting any transformation that learns from their contents. This includes missing-value imputation, scaling, vocabulary construction, dimensionality reduction, and feature selection. Even a transformation that ignores labels can leak information about the held-out distribution.
For example, learn a numeric feature’s mean and standard deviation from the training set, then use those fixed values to transform validation and test data. During cross-validation, fit preprocessing separately inside each training fold. A pipeline that bundles preprocessing with the model helps enforce this boundary.
Apply oversampling and synthetic-example generation only within the training portion. Augmented versions of the same image, recording, or document should not cross split boundaries. Target encoding needs particular care: training-row encodings should avoid using those rows’ own targets, commonly through out-of-fold construction.
Check for Leakage Hidden in the Data
Duplicates and near-duplicates can inflate evaluation scores by turning generalization into recognition. Establish a consistent policy for removing duplicates or assigning related records to the same partition. Watch for overlapping text chunks, repeated photographs, copied support tickets, and multiple exports of the same event.
Another common problem is target leakage through feature timing. A field may look legitimate in a historical table but become available only after the outcome being predicted. For a cancellation prediction, a cancellation-processing status would be inappropriate if it does not exist at prediction time. Review features against their actual availability, not simply their presence in storage.
Time-based tasks also require attention to rolling windows and label periods. A training example whose outcome depends on events beyond the training cutoff may expose future information. Where needed, leave a gap between partitions or exclude overlapping examples, with the gap determined by the task’s observation and outcome windows.
Lock the Workflow Before Opening the Test Set
Document the prediction moment, split method, preprocessing rules, selection metric, and decision threshold before final testing. Once choices are fixed, you may refit the selected pipeline on training and validation data together, then evaluate it on the untouched test set.
Report results with the split’s limitations: one holdout cannot guarantee performance under every future shift. If test findings prompt further development, treat that set as development evidence and seek a fresh independent evaluation. The goal is not the highest visible score, but a credible estimate of behavior on genuinely unseen data.


