Start with a bounded task, not a broad ambition
An AI system can produce an impressive answer and still be a poor fit for everyday work. Demonstrations usually show what is possible; evaluation reveals how consistently a system performs under realistic conditions. Before automating a process, define a narrow task with an identifiable input, expected output, and responsible owner.
For example, “improve customer support” is too broad to test. “Draft replies to delivery-status questions using approved order information” is more useful. It establishes which requests belong in the workflow, what information the system needs, and where its authority ends. Refund decisions, account changes, and unusual complaints can remain outside that boundary.
Also ask whether generative AI is necessary. A fixed rule, search interface, or conventional script may handle predictable work more reliably. AI is often worth testing when inputs vary substantially or involve interpreting language, but that flexibility introduces uncertainty that the evaluation must address.
Define success and establish a baseline
Write down what a successful result must accomplish before comparing tools or adjusting prompts. For a support draft, requirements might include answering the actual question, using the correct order details, avoiding unsupported promises, and following the organization’s tone. Separate essential conditions from preferences: an inaccurate delivery date is not equivalent to an awkward sentence.
Measure the existing process on the same terms. Consider completion time, correction effort, unresolved cases, and the quality of the final result. If employees already use templates, compare the AI-assisted workflow against those templates rather than against an artificially slow manual process. The relevant question is whether AI improves the real alternative.
Include the full cost of using the system. A draft generated quickly may save little time if someone must verify every detail. Track review and rework alongside generation speed, service costs, and maintenance effort. Set acceptance criteria in advance so a polished demonstration does not quietly replace the original business objective.
Build a test set that reflects everyday difficulty
Create a collection of examples that represents the work the system will encounter. Include common requests, incomplete inputs, ambiguous wording, and cases that should be escalated rather than answered. Use appropriately protected data, removing sensitive details where possible. Artificial examples can help explore edge cases, but they should not be the only evidence of usefulness.
Keep some examples separate from prompt development. Repeatedly adjusting instructions to fix the same small collection can make performance look stronger than it is. A held-back test set helps reveal whether an improvement generalizes to unfamiliar inputs. Refresh that set when the workflow changes, while retaining a stable core for comparisons.
Test information boundaries as well as ordinary accuracy. If the system reads emails, documents, or web content, include material containing misleading instructions. Retrieved content should be treated as data, not as authority to change the task or reveal information. Check how the workflow handles missing evidence, conflicting records, and requests beyond its permitted scope.
Score failures by consequence, not just frequency
A single overall quality score can hide important weaknesses. Record separate outcomes for factual correctness, completeness, instruction following, appropriate escalation, and usable formatting. Where possible, use deterministic checks for concrete requirements, such as required fields or valid identifiers. Reserve human judgment for qualities that cannot be checked reliably with simple rules.
Distinguish minor defects from serious failures. A repetitive phrase may be easy to fix; exposing confidential information or taking an unauthorized action is a different category of problem. Define which failures block deployment regardless of average performance. For open-ended work, give reviewers clear examples of acceptable and unacceptable outputs to reduce inconsistent scoring.
Because generated responses can vary, test selected inputs more than once when consistency matters. Another AI model can assist with evaluation, but its judgment should not automatically be treated as ground truth. Check automated grading against human review, especially for subtle errors. Keep a failure log that points to actionable causes rather than merely collecting bad answers.
Introduce automation gradually and keep testing
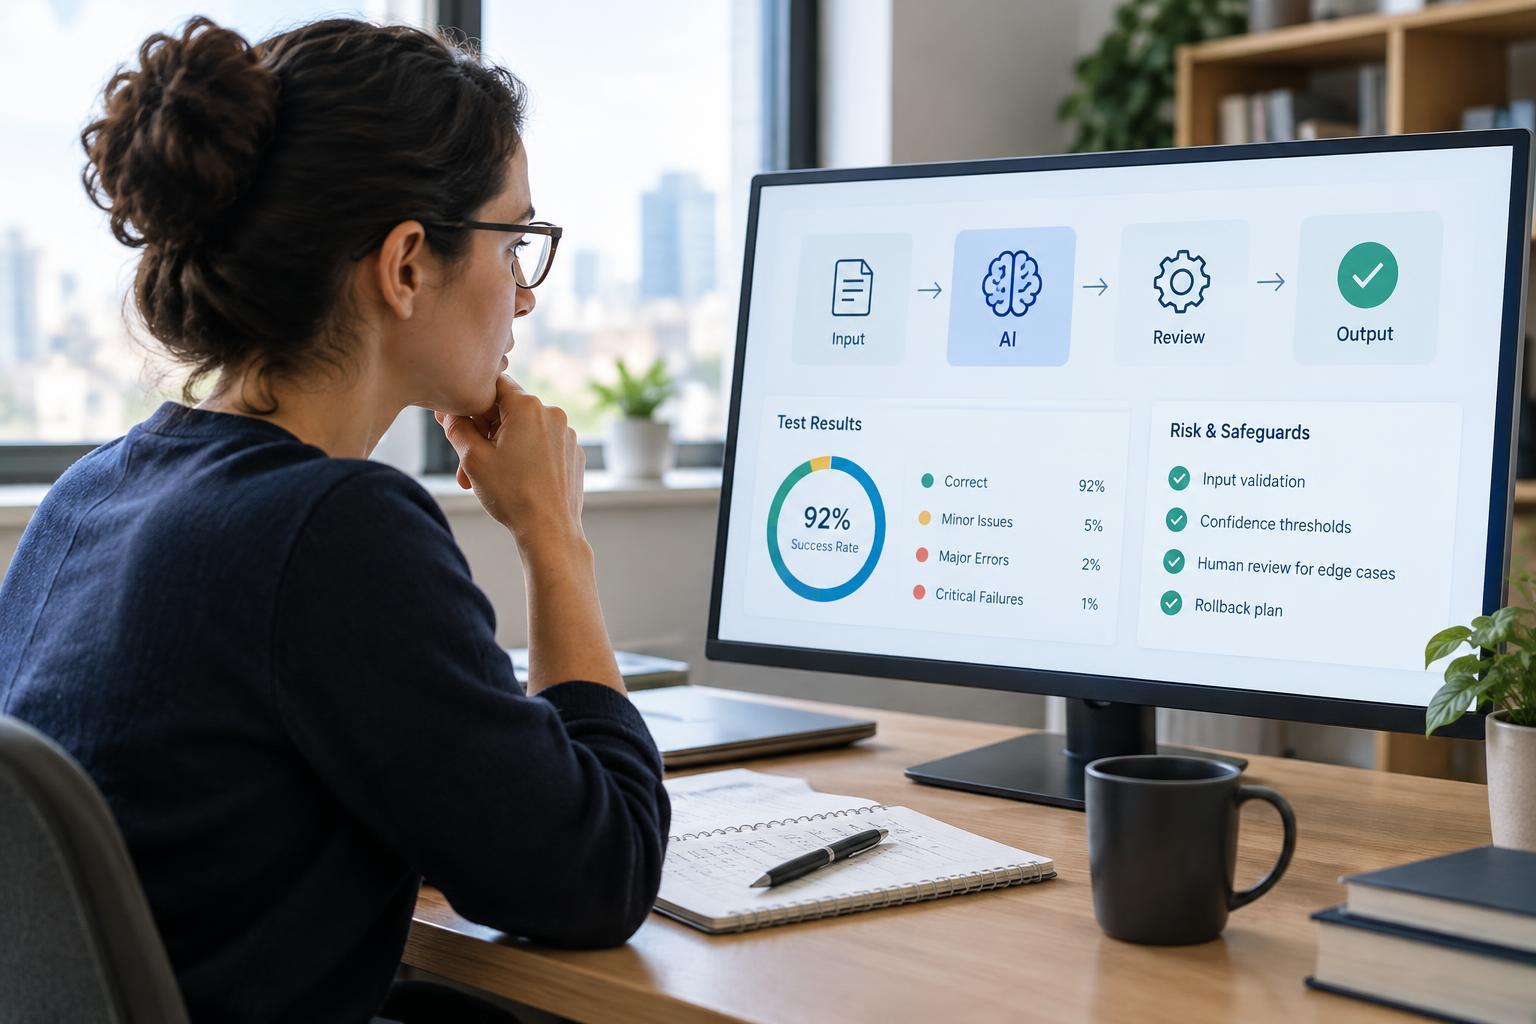
Start with a limited pilot in which people approve outputs before they reach customers or change records. For consequential actions, technical permissions and approval gates matter more than instructions telling a model to be careful. Give the system only the access it needs, and make it possible to pause the workflow or return to the previous process.
Expand responsibility only when the evidence supports it. Continue sampling outputs and watching for changes in error patterns, correction time, and escalation behavior. Re-run evaluations after changing the model, prompts, tools, or reference material. A workflow is ready for broader automation when it delivers repeatable value within clear limits—not simply when it occasionally produces an excellent answer.


