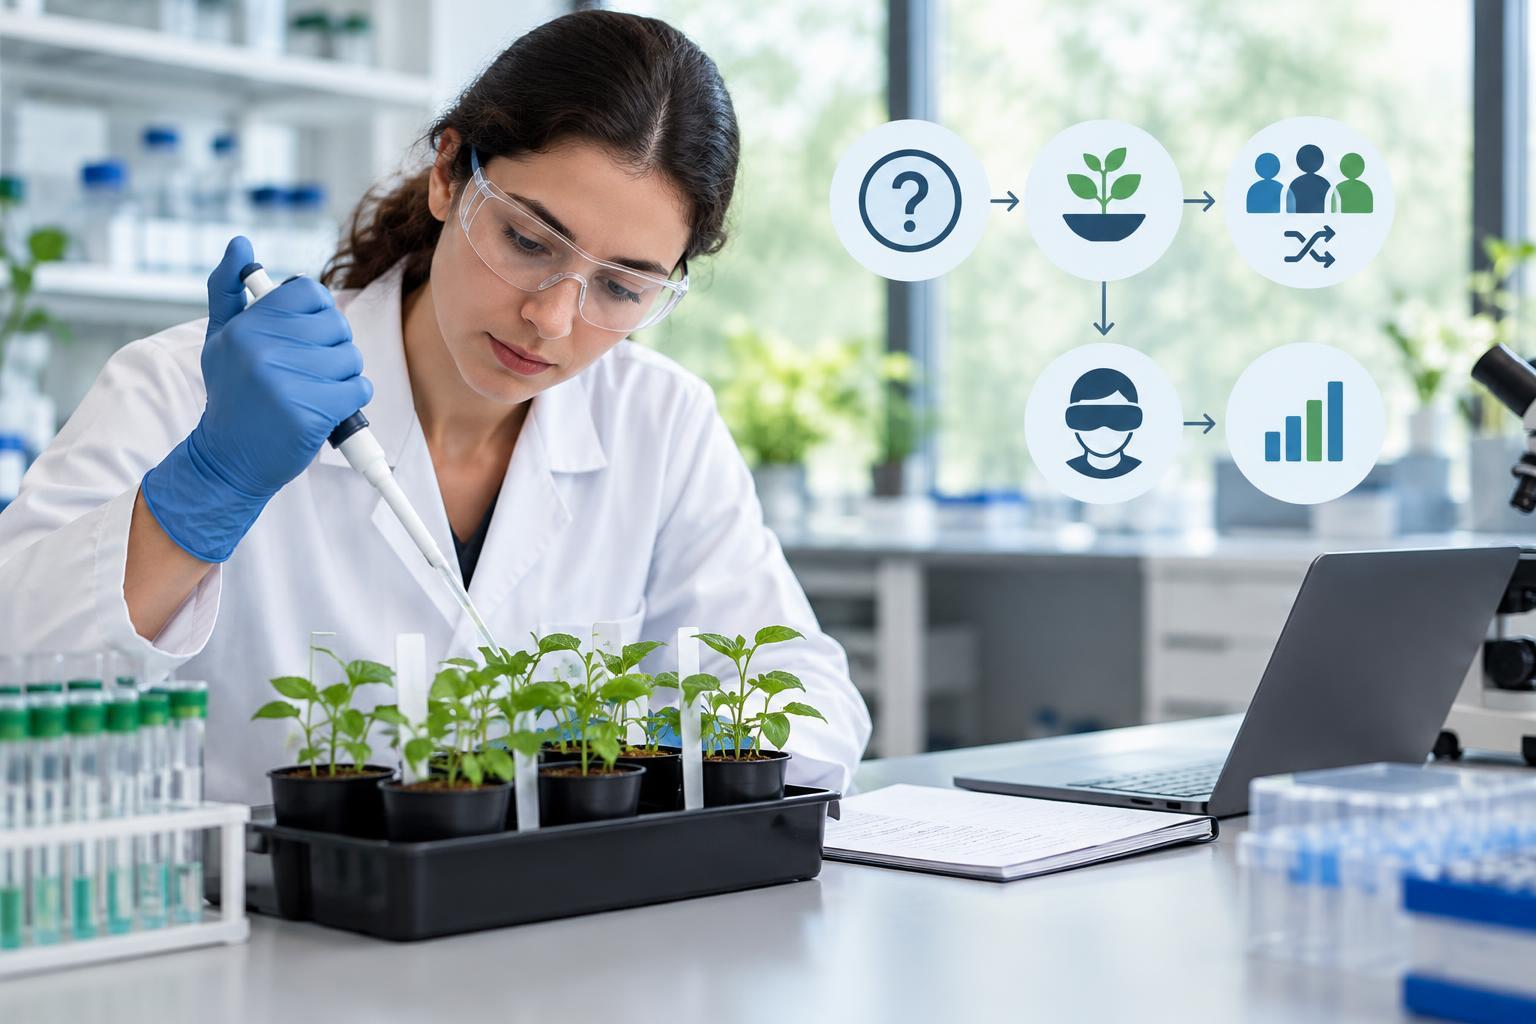
1. Start with a Question You Can Actually Test
A controlled experiment tests whether changing one factor produces a measurable change in an outcome. Its strength comes from comparison: one group receives a treatment or intervention, while another provides a reference. The goal is to make the groups comparable enough that a difference in outcomes can reasonably be attributed to the treatment.
Begin with a specific question rather than a broad ambition. Instead of asking, “What helps plants grow?”, ask, “Does adding a particular fertilizer increase the dry mass of bean seedlings compared with adding no fertilizer under otherwise similar conditions?” This identifies the treatment, comparison, and outcome.
Write a hypothesis before collecting data. Specify the expected direction of the effect, how growth will be measured, and when measurement will occur. A fixed endpoint prevents the temptation to stop the experiment when results happen to look favorable.
2. Define Your Variables and Experimental Units
The independent variable is the factor you deliberately change, such as fertilizer treatment. The dependent variable is the outcome you measure, such as seedling dry mass. Controlled variables are conditions you aim to keep consistent, including soil type, pot size, watering schedule, and light exposure.
A confounding variable offers an alternative explanation for an apparent treatment effect. If fertilized plants sit beside a sunny window while untreated plants remain in shade, light and fertilizer become mixed together. You cannot confidently separate their effects. Keep relevant conditions consistent where practical, and use the same measurement procedure for every group.
Also identify the experimental unit: the entity independently assigned to a treatment. If fertilizer is assigned to whole trays, individual seedlings within a tray are not independent treatment replicates. Measuring more seedlings improves information about that tray, but it does not replace independently assigned trays.
3. Choose a Control Group That Answers the Question
A control group establishes what happens without the specific treatment being tested. In the seedling experiment, the control might receive the same water and handling as the treatment group, but no added fertilizer. Ideally, the groups differ only in the factor relevant to the research question.
Controls can take several forms. An untreated control shows the baseline outcome. A vehicle control receives the substance used to deliver a treatment, but not the active ingredient. A positive control receives a treatment expected to produce a response, helping reveal whether the experimental setup can detect that response.
Choose the comparison deliberately. Testing a new fertilizer against no fertilizer asks whether it has an effect under those conditions. Testing it against an established fertilizer asks a different question: how the two perform relative to each other. Neither comparison automatically answers both questions.
4. Randomize Assignment and Manage Known Differences
Randomization means assigning experimental units to groups using a chance-based procedure, rather than convenience or judgment. For example, label the pots and use a random-number generator to allocate them to treatment or control. Random assignment reduces systematic allocation bias and helps distribute both known and unknown differences across groups.
Randomization does not guarantee balanced groups, especially in small experiments. When a known factor strongly affects the outcome, blocking can help. You might group seedlings by initial size, then randomly assign treatments within each size group. This makes the treatment comparison less vulnerable to starting-size differences.
Consider placement and measurement order too. Randomizing pot positions or balancing treatments across shelves can reduce location effects. Random assignment is different from random sampling: assignment supports causal comparisons within the experiment, while sampling influences how well results may generalize to a broader population.
5. Use Blinding to Reduce Expectation Bias
Blinding limits knowledge of treatment assignments where that knowledge could influence behavior or judgment. A person who expects fertilizer to work might unconsciously give treated plants more attention or interpret borderline measurements differently. Coded labels can keep the person measuring outcomes unaware of which plants received fertilizer.
Depending on the experiment, participants, treatment administrators, outcome assessors, or data analysts may be blinded. Describe exactly who is blinded rather than relying only on labels such as “double-blind,” whose meaning can vary. Keep the assignment key separate until the relevant measurements or decisions are complete.
Full blinding is not always possible. A visible treatment may reveal itself immediately. In that case, use standardized procedures, objective measurements, automated recording where appropriate, and blinded assessment when feasible. Blinding and randomization address different sources of bias; neither substitutes for the other.
6. Plan the Analysis Before Running the Experiment
Before starting, define the primary outcome, measurement schedule, exclusion rules, and analysis approach. Plan enough independent experimental units to detect a scientifically meaningful effect with useful precision. Suitable sample size depends on expected variability and effect size; there is no universal minimum.
A small pilot can uncover practical problems, such as unreliable equipment or inconsistent watering. During the main experiment, record deviations, missing measurements, and equipment failures. Do not silently remove inconvenient observations. Distinguish planned analyses from exploratory questions that arise after seeing the results.
Finally, report the size of the observed effect and its uncertainty, not just whether a test crosses a significance threshold. A statistically inconclusive result does not prove that no effect exists. Interpret findings within the tested conditions, and use independent replication to assess whether the pattern holds beyond one experimental run.


