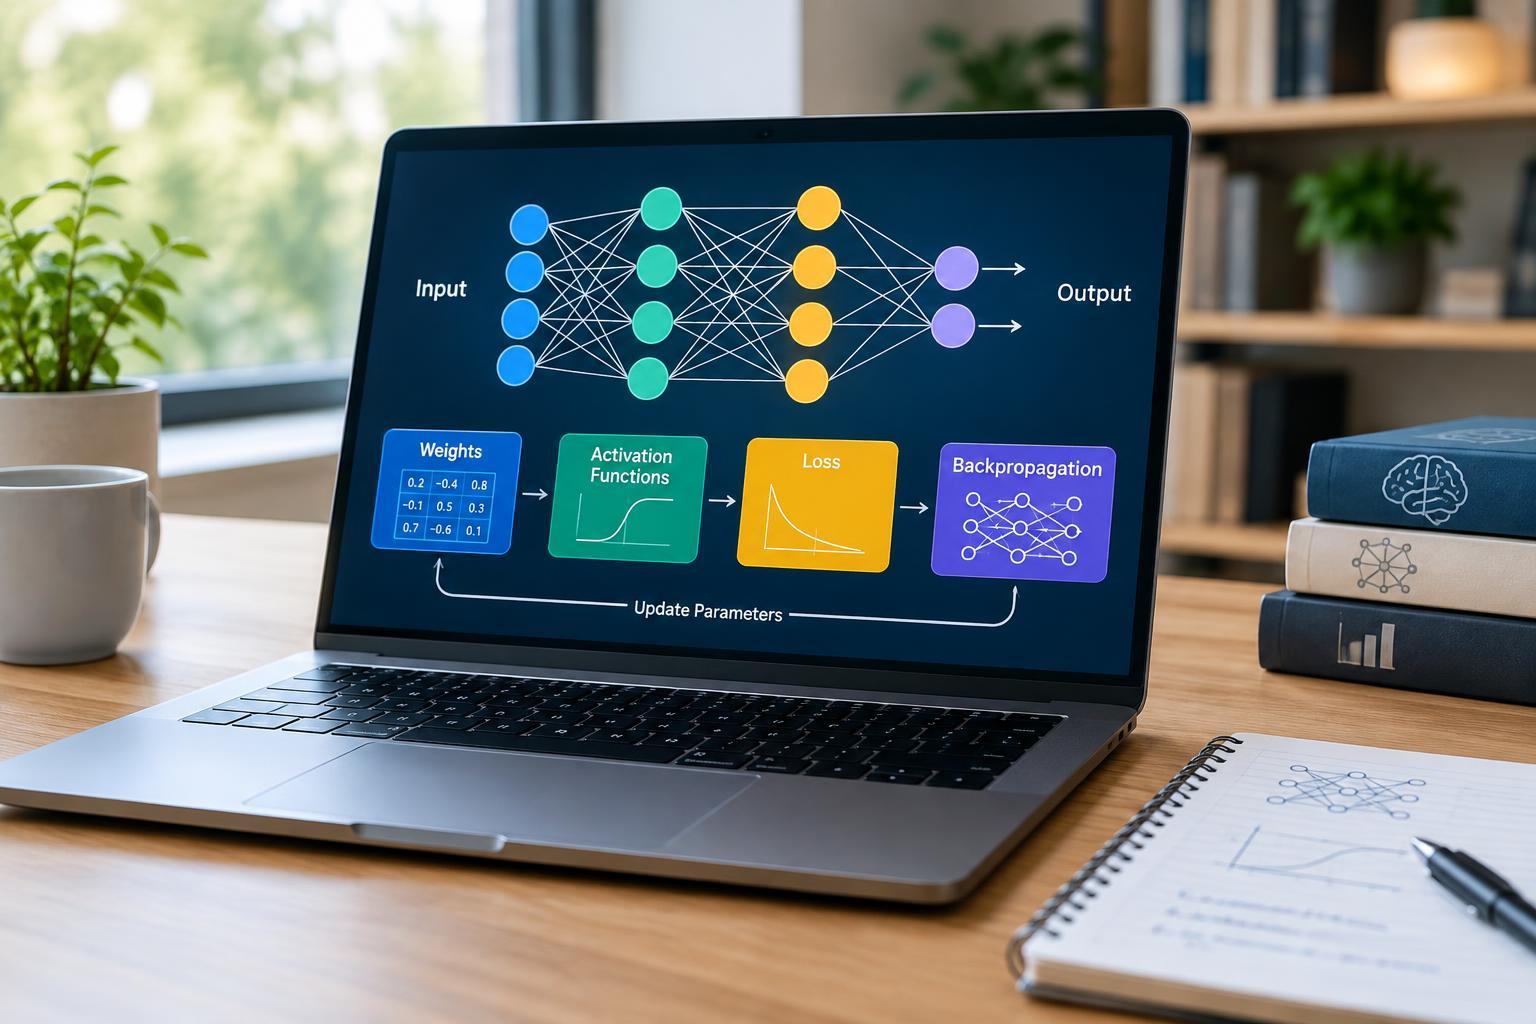
1. Weights Turn Inputs into Predictions
A neural network is a mathematical model that maps inputs to outputs. Inputs might represent image pixels, measurements from a sensor, or numerical representations of words. During training, the network adjusts its internal parameters so its outputs better satisfy a learning objective. Consider a simple network that predicts whether an equipment fault is likely from temperature and vibration readings.
Inside a typical layer, each artificial neuron multiplies its inputs by adjustable numbers called weights, adds the results, and includes another adjustable number called a bias. If two input values are 2 and 3, their weights are 0.5 and −1, and the bias is 1, the weighted sum is −1. Weights determine how strongly inputs influence this calculation; the bias shifts the result.
A network connects many such calculations across layers. Early layers transform the original inputs, and later layers combine those transformed values into a prediction. Weights are usually initialized with small random values using methods designed to keep signals manageable. Learning then modifies those values rather than following a hand-written rule for every possible input.
2. Activation Functions Add Nonlinearity
After calculating a weighted sum, a neuron typically applies an activation function. This function determines the value passed onward. Its crucial role is often to introduce nonlinearity: the ability to represent relationships that cannot be captured by a single linear transformation. Without nonlinear activations or other nonlinear operations, stacking ordinary weighted layers would still amount to one affine transformation, regardless of depth.
One common activation is ReLU, short for rectified linear unit. It returns zero for negative inputs and leaves positive inputs unchanged. In the previous example, a weighted sum of −1 would therefore become zero. Across many neurons, this simple operation helps the network build flexible, input-dependent patterns. Its derivative is straightforward away from zero; software uses a defined convention at that point.
Other functions serve different purposes. Sigmoid maps a value between zero and one and is often used for binary classification outputs. Softmax converts a vector of scores into positive values that sum to one, useful when choosing among mutually exclusive classes. These outputs can be interpreted as model probabilities, but they are not automatically well calibrated.
3. A Loss Function Measures the Mistake
Running inputs through the network to obtain an output is called the forward pass. In supervised learning, training examples also contain target answers. A loss function compares predictions with those targets and produces a numerical measure of error. For the equipment example, the target could indicate whether a fault actually occurred.
Different tasks need different losses. Mean squared error is common for predicting numerical quantities: it squares prediction errors and averages them. Cross-entropy is commonly used for classification, penalizing predictions that assign low probability to the correct class. The choice matters because it defines what the training process is trying to improve.
Loss is a training signal, not a complete measure of usefulness. A model can achieve a low average loss while performing poorly on rare cases or a particular operating condition. Evaluation should therefore include measures that reflect the intended task, alongside checks on examples that were not used to update the model.
4. Backpropagation Calculates How Parameters Affect Loss
Once the loss is known, the network needs to determine how each parameter contributed to it. Backpropagation efficiently calculates derivatives of the loss with respect to weights and biases. It works backward through the computation, applying the chain rule from calculus to connect each intermediate operation to the final loss.
These derivatives form a gradient. Each component describes how a small change in one parameter would affect the loss locally, with other parameters held fixed. A positive derivative means a small increase in that parameter would increase the loss; a negative derivative suggests the opposite. Backpropagation computes these sensitivities—it does not itself decide the update rule.
An optimizer uses the gradients to change parameters. Basic gradient descent subtracts the gradient multiplied by a learning rate. This rate controls the update size: excessively large steps can destabilize training, while very small ones can make progress slow. Optimizers such as Adam adapt updates using information from previous gradients, but they still depend on those gradients.
5. Repetition Builds a Model That Must Generalize
Training repeats the forward pass, loss calculation, backpropagation, and parameter update. It commonly processes small groups of examples called mini-batches rather than the entire dataset at once. Each batch provides an estimate of the training objective’s gradient. One complete pass through the training dataset is called an epoch.
Reducing training loss is not enough. A network may memorize peculiarities of its examples instead of learning patterns that transfer to new inputs. This is overfitting. Validation data helps guide choices such as training duration and model size, while a separate test set supports a final assessment. Regularization, appropriate data augmentation, and early stopping can also help.
The central learning loop is simple: predict, measure error, calculate sensitivities, and adjust parameters. Useful learning still depends on suitable data, objectives, architecture, and evaluation. Once training finishes, ordinary inference uses the learned parameters to make predictions without updating them.


