The Core Idea: Learn to Reverse Corruption
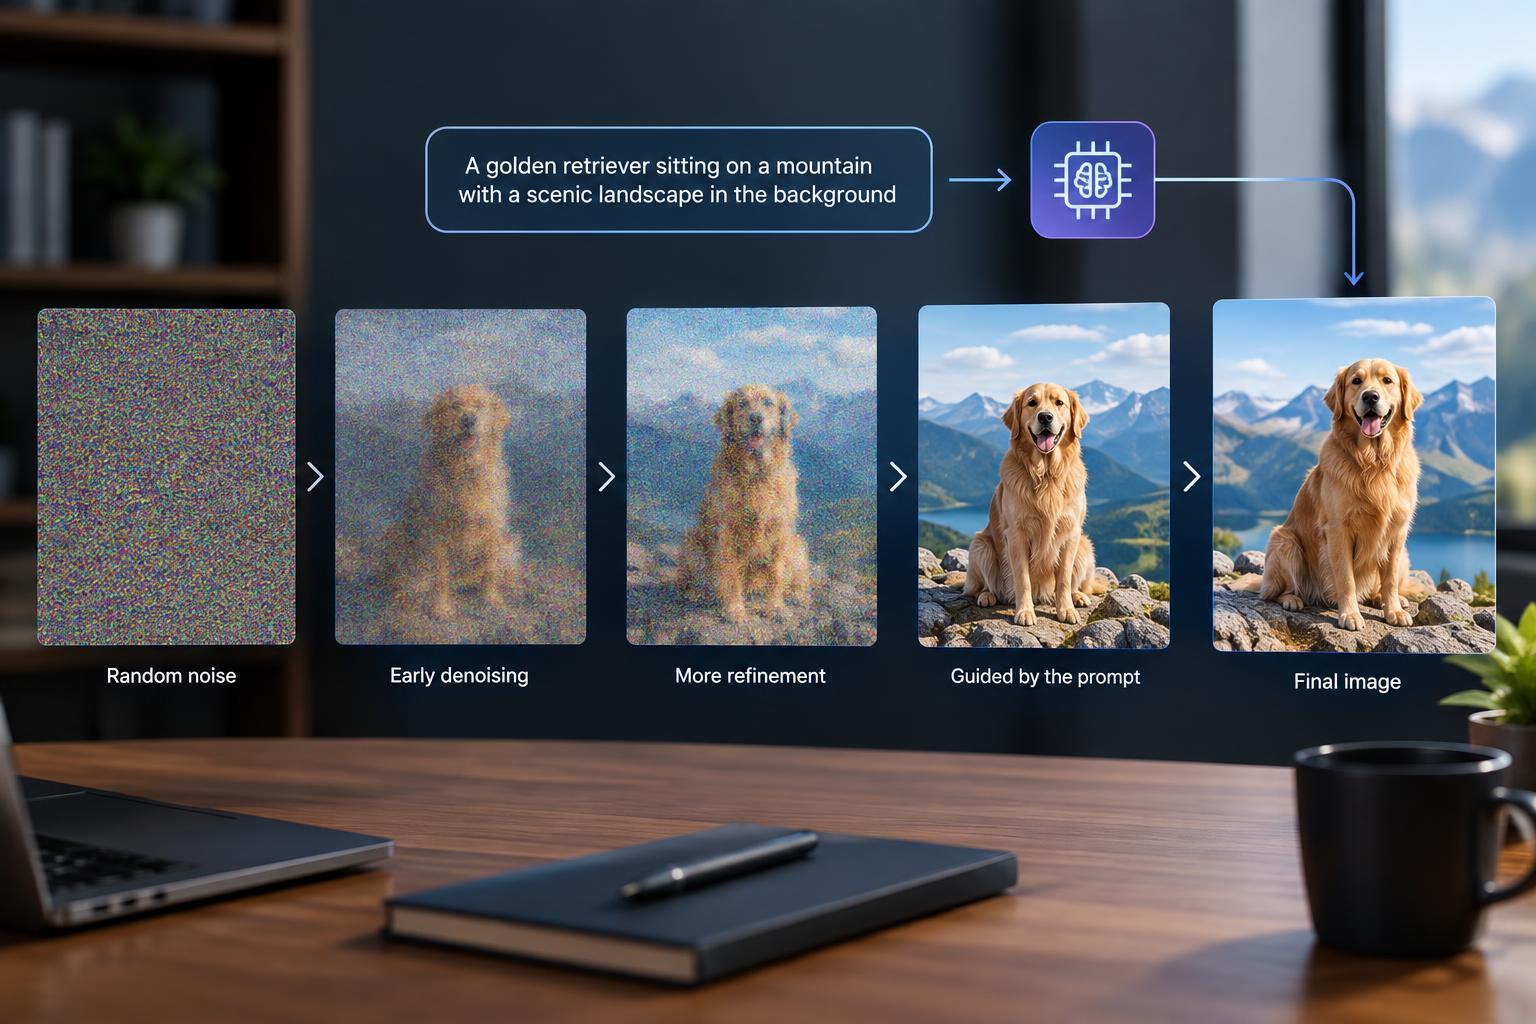
A diffusion model generates an image by starting with random noise and progressively turning it into a structured visual result. Instead of drawing objects with explicit rules, it learns patterns from training images: textures, shapes, lighting, spatial relationships, and associations between images and descriptions. Generation uses those learned patterns to guide a sequence of updates.
The central training idea is to make images noisy in a controlled way. Imagine taking a photograph and gradually mixing in random static. At first, the subject remains recognizable. As more noise is added, fine details disappear, then larger structures become difficult to distinguish. At sufficiently high noise levels, the corrupted image resembles random noise.
Because the training system knows how it corrupted each example, it can train a neural network to help reverse that corruption. This does not mean the network learns a perfect undo button for every image. It learns how to estimate a useful direction toward plausible image content at different noise levels. During generation, there is no original photograph waiting underneath the static.
What the Model Learns During Training
A typical training step takes an image, selects a noise level, and adds a known amount of random noise. The network receives the noisy representation and information about that noise level. Depending on the model design, its target may be the added noise, the clean image, or another mathematically related quantity. Predicting added noise is a common approach, but it is not universal.
The training objective measures how far the prediction is from the target. Repeated updates adjust the network so that its estimates become more useful across many examples and noise levels. Higher-noise inputs require reasoning about broad possibilities, while lower-noise inputs provide more visual evidence for refining detail. These capabilities overlap rather than forming a strict object-first, texture-second sequence.
Many practical systems use latent diffusion. An encoder first compresses images into a smaller numerical representation called a latent. The diffusion network learns to denoise this representation rather than full-resolution pixels, reducing computational demands. After generation, a decoder converts the resulting latent into an image. This compression is useful, although it can introduce its own limitations and artifacts.
How a Text Prompt Steers the Image
For text-to-image generation, a text encoder converts the prompt into numerical representations that the denoising network can use. These representations convey information about concepts and relationships in the description. Through mechanisms such as attention, the image-generation network incorporates that information while processing the noisy image or latent.
A prompt such as “a red bicycle beside a brick wall in soft morning light” therefore conditions the denoising process. It makes certain visual outcomes more likely, but it is not a precise scene specification. A model may capture the bicycle and lighting while mishandling a spatial relationship or object detail. Text conditioning provides direction, not a guarantee of literal compliance.
A common technique called classifier-free guidance strengthens that direction. In a standard setup, the model produces predictions with and without text conditioning. The sampling process then emphasizes the difference between them. Increasing guidance can improve prompt adherence, but excessive guidance may reduce variety or create harsh colors and visual artifacts. Some systems also support negative prompts as an alternative reference condition; these influence generation rather than reliably forbidding an element.
From Random Seed to Finished Image
Generation usually begins with random noise determined by a seed. A sampler then applies a sequence of model predictions and updates, following a schedule of noise levels. The neural network estimates what should change; the sampler determines how to use that estimate to move toward a cleaner result. Some sampling methods introduce additional randomness, while others are deterministic given the same starting state and configuration.
The number of sampling steps affects the trade-off between computational cost and output quality. Too few steps can leave a result underdeveloped, but more steps do not improve every image indefinitely. Different samplers and models require different settings, and some models are specifically trained to work with very few steps. After the final update, a latent-based system decodes its representation into visible pixels.
Keeping a seed fixed is useful when comparing prompts or settings because it controls one source of variation. It does not guarantee identical results across different model versions, software implementations, or hardware configurations. For a practical comparison, keep the model, resolution, sampler, and other settings fixed too.
What This Means for Everyday Use
Effective prompting starts with a clear subject, relevant relationships, and a few important visual attributes. Add composition, lighting, or style when they matter. Avoid relying on long lists of loosely connected adjectives to solve structural problems. Change one element at a time when testing, and remember that an unsuccessful result may reflect a model limitation rather than a poorly written prompt.
Diffusion models produce plausible visual patterns, not verified depictions of reality. They can struggle with exact counts, readable text, anatomy, and complex spatial arrangements. Inspect those details before using an output, and consider targeted editing when the overall image works but one region does not. The key mental model is guided reconstruction from noise: powerful for visual exploration, but not equivalent to a renderer that obeys every constraint.


