Start with the question, not the chart
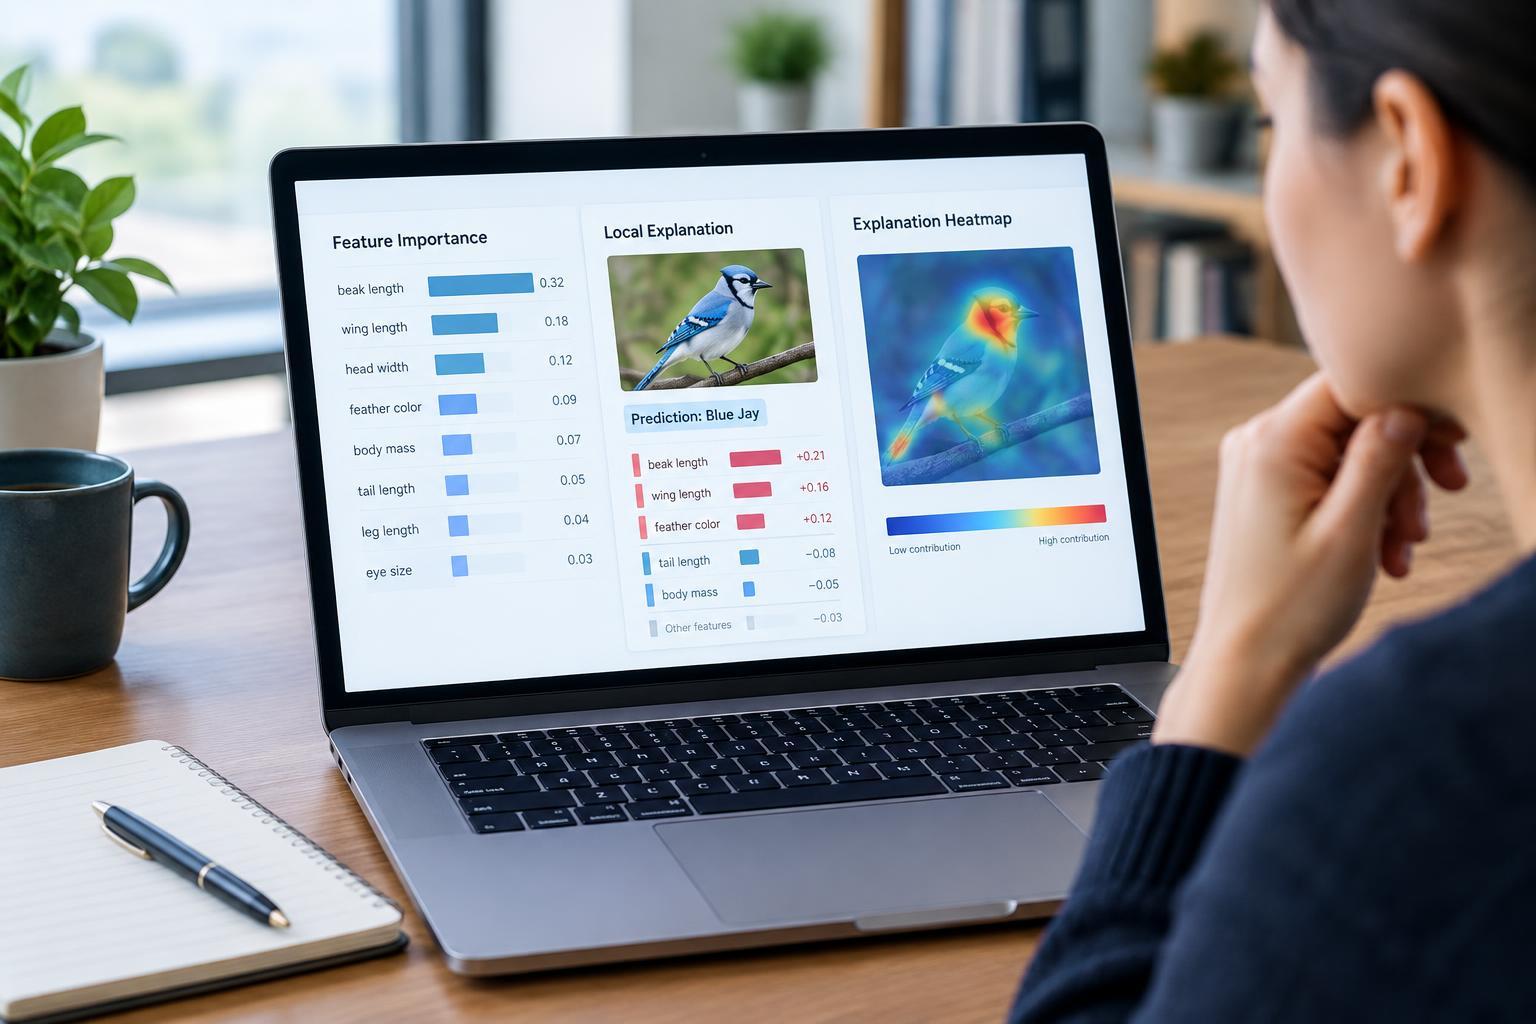
Explainable AI is a collection of approaches for making model behavior easier to understand. An explanation might show which inputs influence predictions across a dataset, why one case received a particular score, or how predictions change when an input changes. These are different questions, and no single chart answers all of them.
Global explanations summarize behavior across many cases. Local explanations focus on one prediction or a small neighborhood of similar cases. A feature that matters little on average can be decisive for a particular case, while a globally important feature may contribute little to that case’s result.
Explanations also differ in how they are produced. A compact decision tree exposes its prediction rules directly. Post-hoc methods analyze a trained model or approximate its behavior afterward. These can be useful, but they are additional analytical tools, not transparent windows into everything a model has learned.
What feature importance actually measures
Feature importance ranks inputs according to a particular definition of influence. Permutation importance, for example, measures how much a chosen performance metric worsens when one feature’s values are shuffled. If shuffling delivery time substantially reduces the accuracy of a customer satisfaction model, that feature helps the model perform on the evaluation data.
The result depends on the model, dataset, metric, and shuffling procedure. Importance measured on training data can reward patterns that do not generalize, so held-out data is usually a better starting point. Built-in importance measures have their own limitations: some tree-based measures can favor features with many possible split points.
Correlated features make interpretation harder. If two inputs contain similar information, the model may substitute one for the other, making each appear less important when shuffled separately. Shuffling can also create combinations that rarely occur naturally. Grouping related features or using conditional approaches may help, but changes the question being measured. A ranking does not establish whether higher values increase predictions.
How local explanations allocate credit
Local methods try to explain a specific output. SHAP assigns feature contributions relative to a reference value, under assumptions about how features are included or treated as missing. In a compatible setup, those contributions sum to the difference between the model output and the reference value. The output scale matters: contributions may describe log-odds rather than probability.
LIME takes another approach. It generates variations around a case and fits a simpler model to approximate the original model nearby. Its usefulness depends on whether those variations are realistic and whether the simpler model accurately represents behavior in the relevant neighborhood.
Neither method supplies a uniquely correct account independent of its settings. Background data, treatment of dependent features, and neighborhood definitions can change the explanation. For a customer churn prediction, contract length might receive different credit depending on whether the reference group is all customers or customers on similar plans. Report that context alongside the result.
What explanations cannot prove
Feature attribution is not causal evidence. A model may use support ticket volume to predict churn, but reducing recorded tickets would not necessarily improve retention. Ticket volume could reflect unresolved problems rather than cause departures. Establishing what an intervention will do requires additional assumptions and evidence beyond a predictive explanation.
An explanation also does not prove that a model is accurate, fair, or safe. A plausible-looking attribution can accompany an incorrect prediction. Removing a sensitive attribute does not eliminate unfair behavior if other inputs act as proxies. Fairness assessment requires explicit criteria, suitable evaluation data, and attention to how the system is used.
Even counterfactual explanations need care. A tool may identify the smallest input change that flips a decision, but that change may be impossible, outside the person’s control, or unrealistic in combination with other features. Likewise, a fluent explanation generated by a language model is not necessarily a faithful account of the computation that produced its answer.
Use explanations as testable diagnostic tools
Begin with a concrete purpose: debugging a model, reviewing an individual prediction, or checking behavior across groups. Choose an explanation method that addresses that purpose, then document the evaluated data, reference population, output scale, and important settings. Separate what the method measures from the conclusions people might draw.
Test whether the explanation is stable under reasonable changes in samples, backgrounds, or settings. Compare methods where useful, without treating agreement as proof. Inspect surprising features for leakage, data-quality issues, or spurious patterns, and check local approximations against the original model’s behavior.
Finally, pair explanations with ordinary validation: held-out performance, calibration where probabilities matter, subgroup checks, and monitoring after deployment. Present limitations in language the audience can understand. The most useful explanation is not the most persuasive story; it is one that supports scrutiny, reveals uncertainty, and helps people ask better questions about the system.


