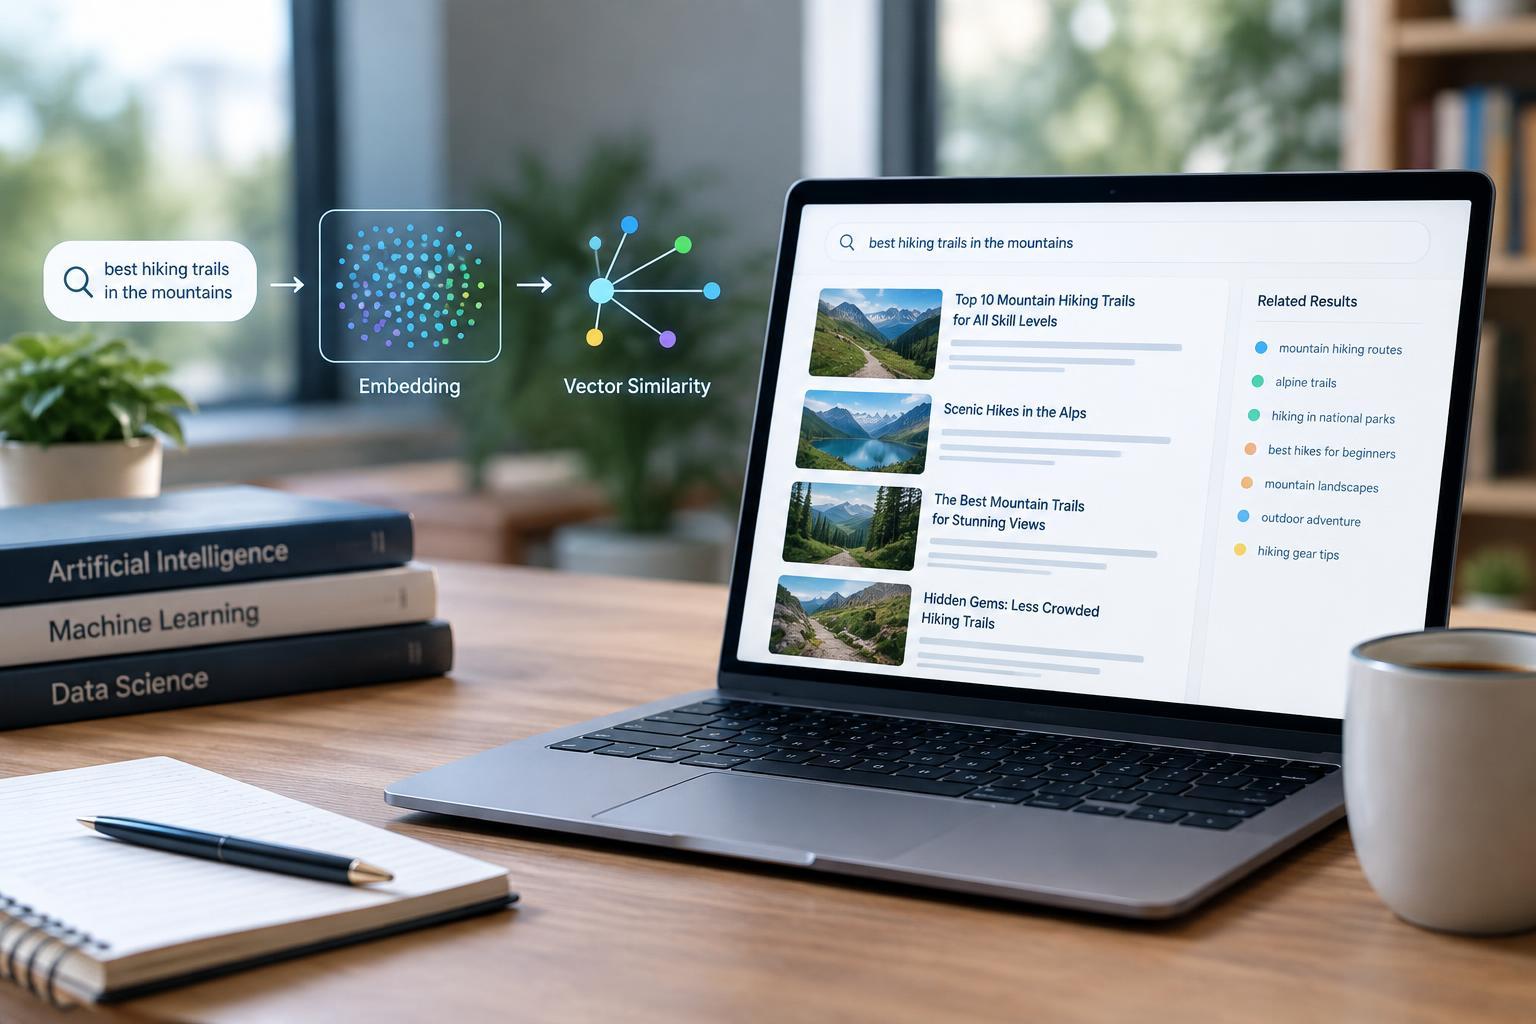
From Matching Words to Matching Meaning
Traditional keyword search is strongest when a query and a document use the same terms. But people often describe the same idea differently. Someone searching for “how to cut electricity bills” might benefit from an article about “reducing household energy consumption,” even though several important words do not match. Semantic search aims to bridge that gap by comparing learned representations of meaning.
This does not mean keyword search is obsolete. Exact terms remain essential for product codes, error messages, names, and specialized terminology. Semantic search adds another way to retrieve useful information: it can connect related phrasing and concepts that literal matching may overlook. Many practical systems combine both approaches rather than choosing one exclusively.
What an Embedding Represents
An embedding is an ordered list of numbers, called a vector, produced by a machine learning model. For text search, the model converts a query, sentence, or passage into a point in a high-dimensional space. Training encourages certain relationships to appear in that space, so text with related meanings or relevance patterns can receive similar vectors.
Individual numbers usually do not have simple labels such as “business” or “science.” Useful information is distributed across the vector. The representation also depends on the model’s training and intended purpose. A model optimized for matching questions to answers may behave differently from one designed to group similar sentences. Some retrieval models also require different formatting for queries and documents.
Embeddings compress information, so they inevitably lose detail. Two passages can be close in vector space while disagreeing on a crucial fact or expressing opposite conclusions. Similarity is therefore a signal of potential relevance, not proof of equivalence, truth, or full human-like understanding.
How Vector Similarity Ranks Results
Once text has been converted into vectors, a search system needs a comparison rule. Cosine similarity measures how closely two vectors point in the same direction, without letting their lengths determine the score. Dot product considers both direction and magnitude, while Euclidean distance measures straight-line separation. For unit-length vectors, these measures produce equivalent rankings under their usual conventions.
The appropriate metric depends on how the embedding model was trained and how its outputs are processed. Using an unsuitable metric can reduce retrieval quality. A similarity score is not a probability that a result is correct, and there is no universal cutoff for relevance. Score ranges and useful thresholds vary across models, datasets, and query types.
Inside a Semantic Search Pipeline
A typical pipeline begins by preparing documents. Long files are divided into smaller passages, often called chunks, and each chunk receives an embedding. The system stores these vectors alongside the original text and metadata such as document title, product category, or access permissions. Chunk boundaries matter: splitting a procedure halfway through can remove context that a search result needs.
When a user submits a query, the system embeds it using a compatible query encoder, then retrieves nearby document vectors. A small collection may support comparing the query against every stored vector. Larger collections often use approximate nearest neighbor indexes, which trade some retrieval completeness for faster searches and lower computational cost.
The system can then rerank a shortlist using a model that examines the query and candidate text together. Results might appear directly in a search interface or become reference material for a generative assistant. This latter pattern is commonly called retrieval-augmented generation, or RAG. Retrieval supplies context, but it does not guarantee that a generated answer faithfully reflects it.
Why Hybrid Retrieval Often Helps
Semantic retrieval can struggle when tiny textual differences carry large meaning. A search for a particular device model should not return a neighboring model simply because their descriptions are similar. Negation, numerical constraints, uncommon vocabulary, and ambiguous queries can also cause problems. Keyword matching and explicit metadata filters can preserve distinctions that embeddings blur.
Hybrid retrieval combines lexical and vector search, then merges or reranks their candidates. For example, a support portal might use semantic similarity to understand “screen keeps going dark,” keyword search to recognize an error code, and metadata to restrict results to the correct product. Authorization must be enforced throughout retrieval and before results reach a user or generating model; it should never depend on similarity alone.
Measuring Quality and Maintaining the System
Evaluate semantic search with representative questions and judgments about which passages actually help answer them. Check whether useful results appear near the top and examine failures involving exact identifiers, missing context, and misleadingly similar passages. Track latency and operating cost alongside relevance. Good performance on a handful of convenient examples does not establish reliability across a real collection.
Maintenance matters too. Changed documents need updated embeddings, deleted content must disappear from retrieval, and model upgrades generally require re-embedding and reindexing stored text unless compatibility is explicitly supported. Treat embeddings as potentially sensitive derived data, not anonymized text. Strong semantic search comes from combining appropriate representations with careful content preparation, evaluation, and access controls.


