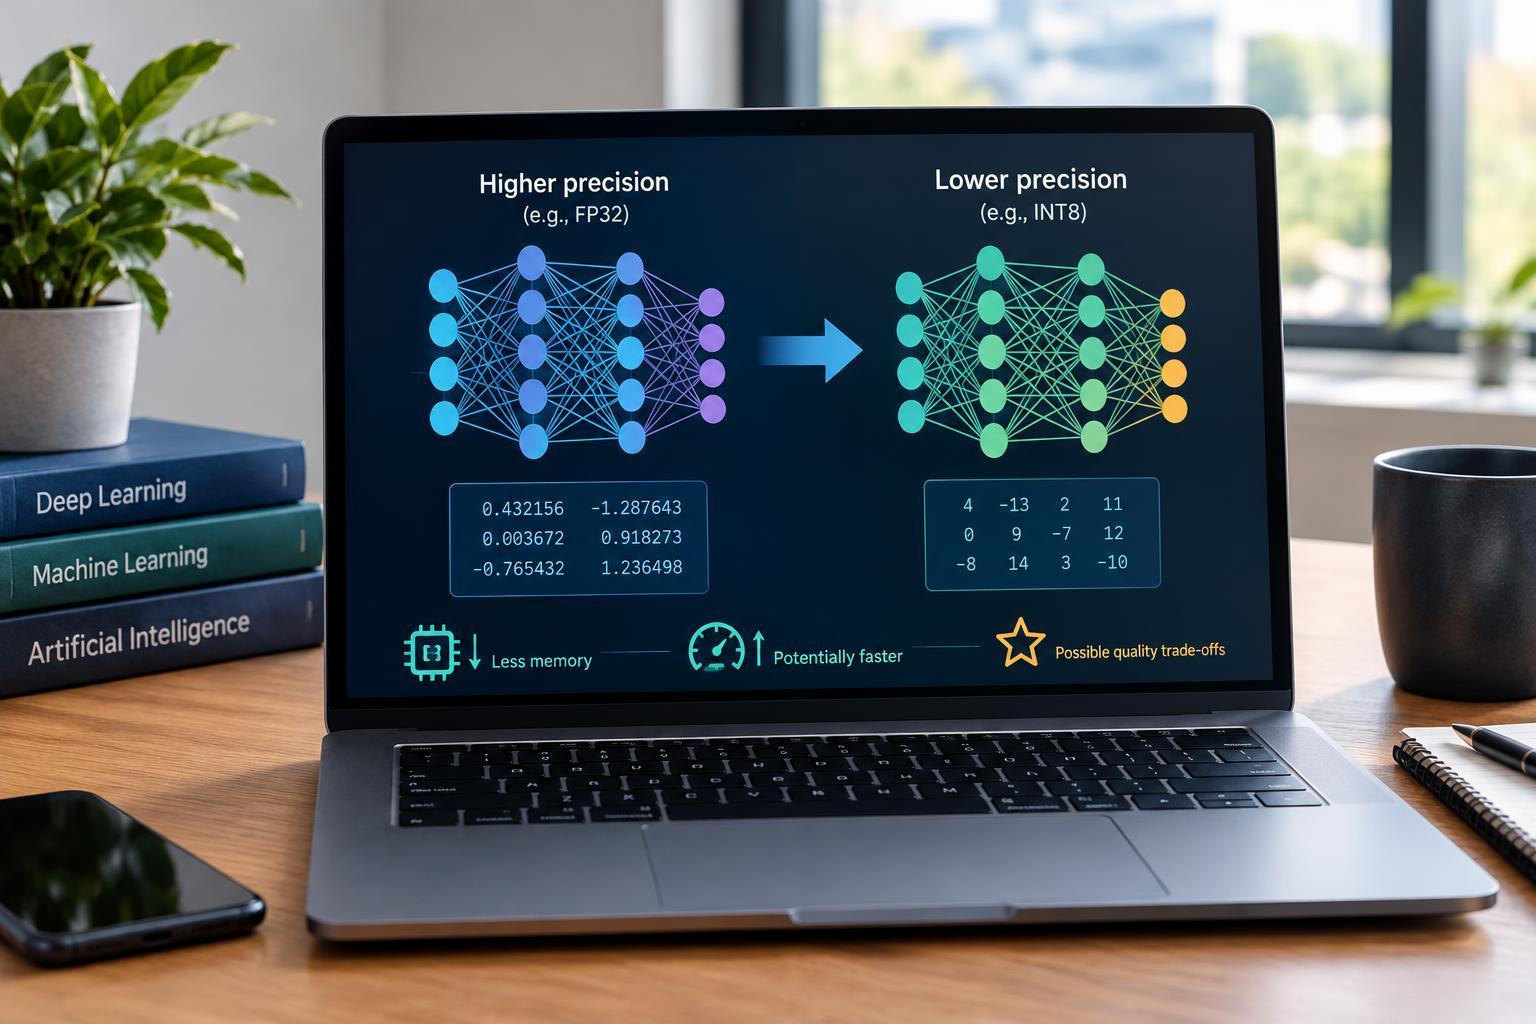
What quantization changes inside an AI model
An AI model contains numerical parameters, often called weights, that influence how it transforms an input into an output. During inference, the model also produces intermediate values called activations. The formats used to represent these numbers affect how much memory the model needs and which calculations a processor must perform.
Quantization represents some of these values using fewer bits or a more restricted set of numerical levels. Instead of preserving a finely detailed value, it stores an approximation. Imagine replacing a ruler with very fine markings with one that has fewer divisions: measurements become less precise, but they can be represented more compactly.
This does not necessarily remove layers, reduce the number of parameters, or change the model’s overall architecture. A quantized model can retain the same basic structure as its higher-precision counterpart. What changes is how accurately selected numbers are represented and, depending on the implementation, how operations involving those numbers are executed.
Why smaller representations can help
The most direct benefit is reduced storage and memory use for the values being quantized. Smaller weights can make a model easier to download, load, and fit into device memory. This can determine whether a particular model runs on available hardware at all, rather than requiring a different device or a smaller model.
Quantization can also reduce the amount of data moved between memory and processing units. That matters because inference performance is not determined by arithmetic alone. In workloads where fetching weights is a bottleneck, moving fewer bytes can improve speed. Hardware with efficient support for low-precision operations may provide additional gains.
However, model weight size is not the same as total runtime memory. Activations, temporary workspaces, software overhead, and cached attention data can also consume substantial space. In language models, that cache generally grows with conversation length and the number of requests processed together. Quantizing weights alone does not shrink every component.
How models are quantized
Post-training quantization applies quantization to an already trained model. Some methods use a representative calibration dataset to estimate useful numerical ranges or identify values that require special handling. Calibration does not simply mean retraining the model; it helps determine how existing values should map into the available lower-precision representation.
Quantization-aware training introduces simulated quantization effects during training or additional fine-tuning. This gives the model an opportunity to adapt to the approximations it will encounter during deployment. It requires more effort and resources than straightforward post-training conversion, but it can help preserve quality when the numerical constraints are demanding.
Not every part of a model must use the same precision. Some approaches quantize weights while keeping activations at higher precision. Others quantize both, or preserve particularly sensitive components in a more precise format. Labels such as “4-bit model” are therefore useful shorthand, but they do not fully describe the implementation.
Why lower precision can affect quality and speed
Quantization introduces approximation error. Many models tolerate some of this error well, but aggressive compression can alter outputs noticeably. Values with unusually large magnitudes can make it difficult to choose a numerical range that also preserves smaller differences. Methods that use separate scales for different groups of values can reduce this problem, although they introduce additional complexity and storage.
Quality changes may be uneven across tasks. A language model might remain useful for routine drafting while becoming less dependable on specialized vocabulary, structured extraction, or demanding reasoning tasks. There is no universal precision level that guarantees acceptable results for every model and application. Testing the actual workload is more informative than relying on the bit count alone.
Smaller is not automatically faster, either. A processor may lack efficient support for the chosen format, or the software may need extra conversions before computation. Specialized execution routines, workload size, and memory behavior all matter. A quantized version can save memory without improving latency, and some configurations may even run more slowly.
How to choose a quantized model in practice
Begin with a specific constraint: insufficient memory, slow responses, limited storage, or low throughput. Keep a higher-precision version as a comparison point when feasible. Check that the quantized format is supported by the intended hardware and inference software before investing time in detailed evaluation.
Compare versions using representative inputs under similar conditions. Measure peak memory, response latency, and throughput separately. For generative models, inspect task completion and instruction following rather than expecting identical wording. Include difficult examples and realistic input lengths, since a short demonstration can hide weaknesses that appear in normal use.
Choose the least aggressive quantization that meets your operational needs while retaining acceptable quality. Record the model version, quantization method, runtime, and hardware so the result can be reproduced. Treat quantization as an engineering trade-off, not a free upgrade: its value depends on the resources it saves and the behavior it preserves.


